GPT-6 Astra vs Claude Fable 5.1 vs GPT-5.6 Sol: A Tie at 53, and What Breaks It
GPT-6 Astra and Claude Fable 5.1 tie at 53 on the Artificial Analysis Intelligence Index v4.3, with GPT-5.6 Sol at 47. Three charts on cost per task, sub-scores and speed, plus which model to use for which job.
TL;DR: GPT-6 Astra and Claude Fable 5.1 tie at 53 on the Artificial Analysis Intelligence Index v4.3, but Astra gets there on about a third of the output tokens, at $3.26 per task against $7.63. Fable 5.1 still wins science coding, Humanity's Last Exam, long-horizon knowledge work and tool calling. GPT-5.6 Sol, at 47, is the cheaper tool-ready option.
This is the three-way view, with charts. For two-way matchups, see Claude Fable 5.1 vs GPT-6 Astra and GPT-5.6 Sol vs GPT-6 Astra.
Who these three are
- GPT-6 Astra (OpenAI): limited preview 2026-09-03, generally available 2026-09-04. 1,050,000-token context, 128,000 max output tokens, text and image in, text out. More in what GPT-6 Astra is and how to get it.
- Claude Fable 5.1 (Anthropic): released 2026-09-01. The same model as Claude Mythos 5.1 with different safeguards (Mythos is trusted-access only). Effort from Low to Max; available on AWS, Google Cloud and Azure.
- GPT-5.6 Sol (OpenAI): one version number behind Astra, and the baseline Astra must justify its price against. $5 input / $30 output per million tokens standard, on a promotional $4 / $20 at least through November 21, 2026.
The index-version trap: 66 and 53 are both real
On 2026-09-01, Artificial Analysis' launch write-up reported 66 for Claude Fable 5.1 on its Intelligence Index. On 2026-09-07 it published Intelligence Index v4.3, which added harder agentic tests, and Fable 5.1 now scores 53, level with GPT-6 Astra. The ruler changed.
v4.3 combines 10 evaluations: AA-Briefcase, GDPval-AA v2, AutomationBench-AA, Terminal-Bench v4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience and AA-LCR v1.1. A Fable 5.1 score in the 60s next to an Astra score in the 50s is two index versions, not a gap between models. That goes for older posts too, including our July three-way comparison. Every index number below is v4.3. We never mix versions.
One more calibration: all scores here were measured at max or high effort, as labelled. On TulexAI we run GPT-6 Astra at OpenAI's default effort, so treat the benchmarks as what each model does when told to think hard, not a promise about every chat reply.
Intelligence: a tie at the top, Sol six points back
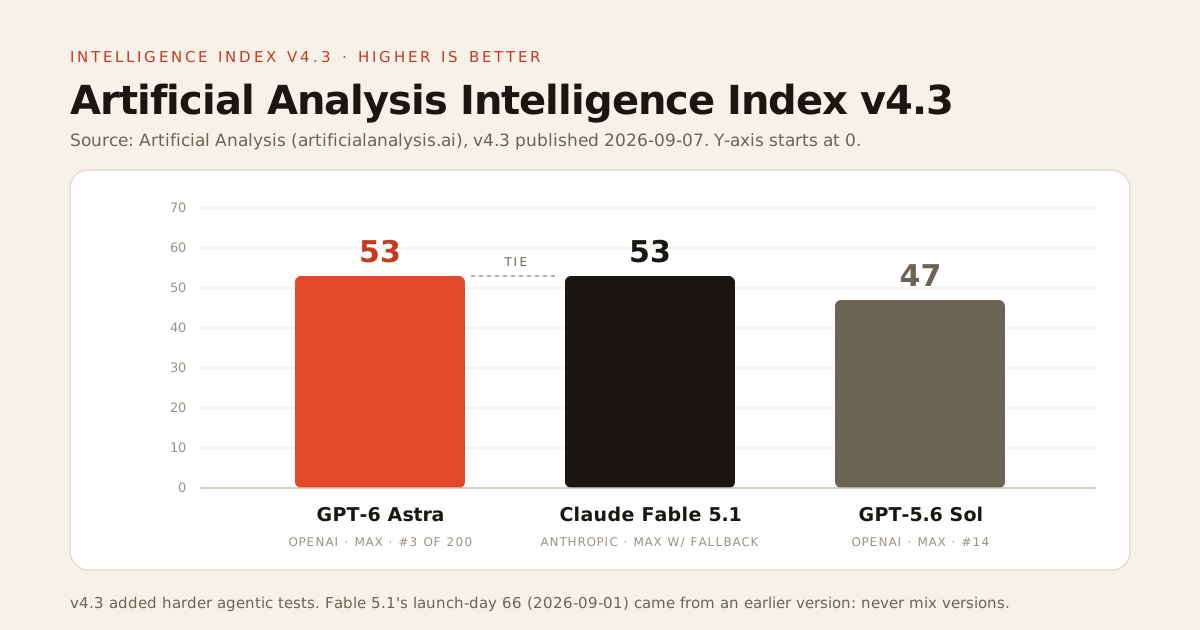
On the v4.3 board of 200 models, Astra at max effort scores 53 and ranks #3. Fable 5.1 at max effort with fallback also scores 53. Sol at max effort scores 47 and ranks #14. Two context points: Astra at high effort scores 51 (#6), and Claude Fable 5, the predecessor, scores 50 with fallback on the same version. Same score, same version, both at max effort: a genuine tie.
Efficiency: the same 53 at less than half the cost
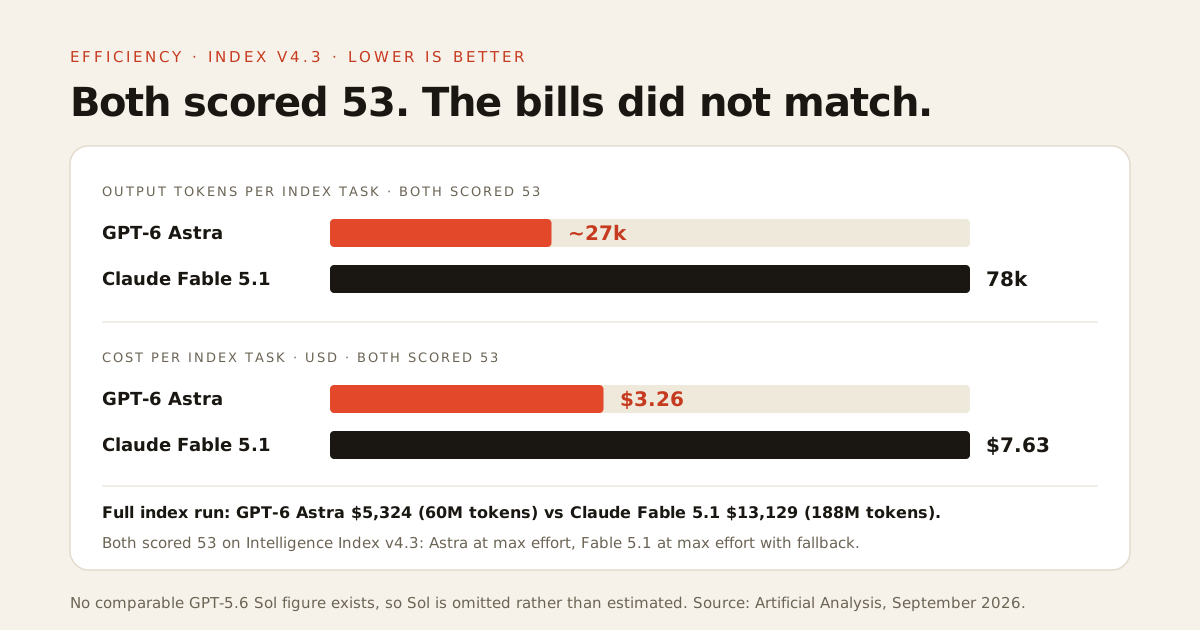
To reach 53, Astra used about 27k output tokens per task. Fable 5.1 used 78k, roughly 2.9 times as many. Both list at $10 input / $50 output per million tokens, so the bill follows the tokens: $3.26 per task for Astra vs $7.63 for Fable 5.1, about 43% of the cost ($3.26 / $7.63) for the same score. The full index run shows it at scale: $5,324 for Astra (60M tokens) against $13,129 for Fable 5.1 (188M tokens), about 2.5 times the spend.
One caveat cuts the other way. Fable 5.1's cache reads cost $0.25 per million tokens, a 75% cut from Fable 5, against $1 for Astra's cached input. Workloads that resend a large, stable prompt win back part of the gap; the per-task figures do not say how much.
Sub-scores: where each one actually wins
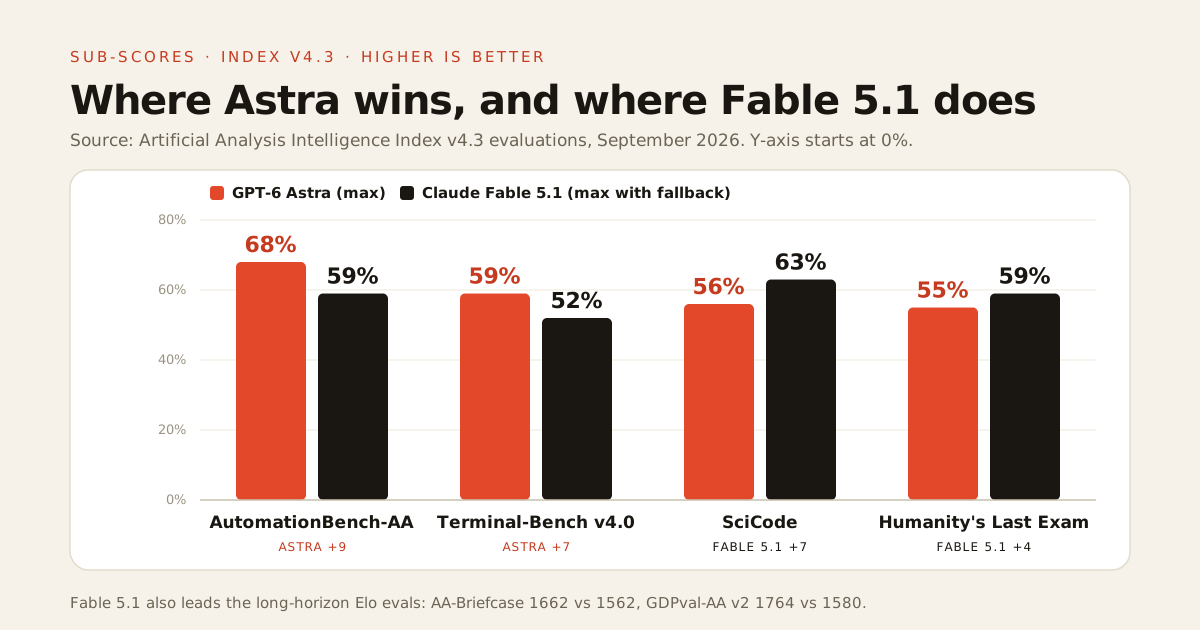
Tied totals hide a clean split. On Artificial Analysis' v4.3 evaluations:
- Astra wins automation and terminal work: AutomationBench-AA 68% vs 59% (+9), Terminal-Bench v4.0 59% vs 52% (+7).
- Fable 5.1 wins science and hard knowledge: SciCode 63% vs 56% (+7), Humanity's Last Exam 59% vs 55% (+4).
- Fable 5.1 wins long-horizon agentic knowledge work, by a wide margin: AA-Briefcase 1662 Elo to Astra's 1562 (+100), GDPval-AA v2 1764 to 1580 (+184).
- Coding agents are a draw: both score 62 on the Artificial Analysis Coding Agent Index.
So "which is smarter" is the wrong question. That split drives the job table below.
GPT-6 Astra vs GPT-5.6 Sol: what the upgrade buys
Per Artificial Analysis:
- +6 on Intelligence Index v4.3: 53 vs 47, both at max effort.
- Hallucination rate falls from 92% to 51% at max effort, Sol to Astra: the largest percentage-point gap in this post.
- +7 on the Coding Agent Index at about 15% more cost per task ($7.09 per task for Astra).
- Mixed long-horizon results: about 90 Elo above Sol on AA-Briefcase, about 45 Elo below Sol on GDPval-AA v2.
- A higher list price: $10/$50 per million tokens vs Sol's standard $5/$30, so twice the input rate and about 1.7 times the output rate. While Sol's promotional $4/$20 lasts (at least through November 21, 2026), Astra is 2.5 times Sol's price.
My read: if wrong answers are expensive for you, the hallucination drop alone justifies Astra. For high-volume, tool-calling work that Sol already handles well, Astra's list-price premium is a hard sell.
Speed: the trade-off nobody headlines
Artificial Analysis' first-token times at max effort include thinking, and that is where these three separate most:
| Model (effort) | Time to first token | Output speed | Index v4.3 |
|---|---|---|---|
| GPT-6 Astra (max) | 334s | 58.1 tok/s | 53 |
| GPT-6 Astra (high) | 37s | 52.4 tok/s | 51 |
| Claude Fable 5.1 | 213s | 65 tok/s | 53 |
| GPT-5.6 Sol (max) | 131s | 58.8 tok/s | 47 |
Astra at max effort thinks for about five and a half minutes before its first token. Fable 5.1 takes about three and a half, Sol just over two. Once text flows they are close, with Fable 5.1 quickest at 65 tokens per second. The row worth a second look is Astra at high effort: 37 seconds, about a ninth of the max-effort wait, for 51 instead of 53. On the API, that is the setting I would use for interactive work.
Vendor claims vs independent numbers
Everything above is Artificial Analysis, an independent third party. Here are the vendors' own claims, labelled as such.
Anthropic, vendor-reported, Claude Fable 5.1: Terminal-Bench 4.0 55.8%; OSWorld 2.0 77.9% partial and 41.7% strict; CursorBench 3.2.0 73.4%; Humanity's Last Exam 60.9% without tools and 65.0% with tools; costs about 25% lower for typical workloads and up to about 45% lower for agentic work than Fable 5. Note the mismatch: Anthropic reports 55.8% on Terminal-Bench 4.0, while Artificial Analysis' independent Terminal-Bench v4.0 run puts Fable 5.1 at 52%. We compare models on the independent figure.
OpenAI, vendor claims, GPT-6 Astra: "the most intelligent and aligned model in the world", and state of the art for computer use, browsing, software engineering, cybersecurity, science and professional work. The announcement names eight benchmarks, from Agents' Last Exam and AutomationBench to TerminalBench-4.0 and HealthBench Pro, but the community post publishes no scores. Independently, Astra is #3 of 200 and level with Fable 5.1: frontier-class, not a clear sole leader.
Tools: the practical decider on TulexAI
OpenAI's reasoning guide is blunt: "Chat Completions does not support function calling with GPT-6 Astra." On TulexAI, Astra runs without tools, and its replies are capped at 8,192 output tokens. Claude Fable 5.1 and GPT-5.6 Sol both support tools. So on TulexAI, the leader on AutomationBench-AA and Terminal-Bench v4.0 cannot call functions for you. Use Astra for reasoning, planning and drafting, and switch to Fable 5.1 or Sol for tool-driven steps. More in Can GPT-6 Astra run agents?
Which model for which job
| Your job | Pick | The number behind it |
|---|---|---|
| Top-score reasoning at the lowest cost per task | GPT-6 Astra | 53 at $3.26 per task vs $7.63 |
| Automation logic and terminal-style tasks, no tool calls | GPT-6 Astra | AutomationBench-AA 68% vs 59%; Terminal-Bench v4.0 59% vs 52% |
| Fewer hallucinations than Sol | GPT-6 Astra | Hallucination rate 51% vs 92% |
| Scientific code | Claude Fable 5.1 | SciCode 63% vs 56% |
| Expert-level questions | Claude Fable 5.1 | Humanity's Last Exam 59% vs 55% |
| Long-horizon knowledge work | Claude Fable 5.1 | AA-Briefcase 1662 vs 1562 Elo; GDPval-AA v2 1764 vs 1580 |
| Coding agents that call tools | Claude Fable 5.1 | Coding Agent Index 62, tied with Astra, plus tools |
| Tool calling on a tighter API budget | GPT-5.6 Sol | $5/$30 per 1M standard ($4/$20 on promotion) vs Astra's $10/$50 |
What it costs
API: GPT-6 Astra and Claude Fable 5.1 both list at $10 input / $50 output per million tokens, with $1 cached input for Astra and $0.25 cache reads for Fable 5.1. GPT-5.6 Sol is $5 / $30 standard, listed at a promotional $4 / $20 at least through November 21, 2026 (OpenAI pricing, checked 2026-09-15).
TulexAI: GPT-6 Astra is 25 PT per 750 tokens on Pro ($23/mo), VIP and Elite, not Basic. Astra's hidden reasoning counts toward those tokens, with a 25 PT minimum per request, so a long or reasoning-heavy answer costs a multiple of 25 PT. Claude Fable 5.1 is also 25 PT per 750 tokens, Pro and up. GPT-5.6 Sol is there too, with tools. One subscription covers all three plus other text, image, video and voice models, and you can switch models mid-chat. See the pricing page, the GPT-6 Astra model page, or our ChatGPT alternative comparison if you are weighing a single ChatGPT plan.
Frequently Asked Questions
Is GPT-6 Astra better than Claude Fable 5.1?
Neither wins outright: both score 53 on Artificial Analysis Intelligence Index v4.3. Astra is cheaper per task ($3.26 vs $7.63) and leads automation and terminal work. Fable 5.1 leads SciCode, Humanity's Last Exam and long-horizon knowledge work, and supports tools on TulexAI.
Why did Claude Fable 5.1 score 66 and now 53?
Different index versions. Artificial Analysis reported 66 on 2026-09-01. Intelligence Index v4.3, published 2026-09-07, added harder agentic tests, and on it Fable 5.1 scores 53, level with GPT-6 Astra. Only compare scores from the same version.
Is GPT-6 Astra worth it over GPT-5.6 Sol?
If accuracy matters, likely yes. Per Artificial Analysis, Astra scores 53 vs 47 on Index v4.3 and cuts the hallucination rate from 92% to 51% at max effort. It lists at $10/$50 per million tokens against Sol's standard $5/$30, and on TulexAI Sol supports tools while Astra does not.
Which of the three is fastest?
At max effort, thinking included, GPT-5.6 Sol reaches first token in 131 seconds, Claude Fable 5.1 in 213 and GPT-6 Astra in 334. Fable 5.1 streams fastest at 65 tokens per second. Astra at high effort cuts first-token time to 37 seconds for a score of 51.
Can GPT-6 Astra use tools or function calling?
Not through Chat Completions: OpenAI's docs say Chat Completions does not support function calling with GPT-6 Astra. On TulexAI, Astra runs without tools, while Claude Fable 5.1 and GPT-5.6 Sol support them.
How much do these models cost on TulexAI?
GPT-6 Astra and Claude Fable 5.1 are each 25 PT per 750 tokens on Pro ($23/mo) and above; neither is on Basic. GPT-5.6 Sol is also available on TulexAI, with tools.
Settle the tie on your own prompts. GPT-6 Astra, Claude Fable 5.1 and GPT-5.6 Sol sit on one TulexAI subscription, with switching mid-chat. See plans (Astra and Fable 5.1 start on Pro at $23/mo) or create your account.
Ready to consolidate your AI tools?
40+ AI models - GPT-5.6, Claude Opus 5, Gemini, Flux, Sora & more. One subscription from $11/mo.
Try 1 Free PromptContinue reading
What Is Claude Opus 5.5? What Changed, What It Costs, and Where It Falls Down
Anthropic's Claude Opus 5.5 costs 20% less per token than Opus 5, and Anthropic says it performs at the level of Claude Fable 5.1 on most work. What changed, what it costs on the API and on TulexAI, where it falls down, and every way to get it.
What Is GPT-6 Astra? OpenAI's New Flagship, and How to Actually Get It
OpenAI's GPT-6 Astra ties Claude Fable 5.1 on the neutral scoreboard, but ChatGPT Plus only gets it in Work and Codex. What it is, every way to access it, what it costs, and the catches.